Transformer Networks, Explained to Computer Vision brains! 🧠
Breakthrough Attention!
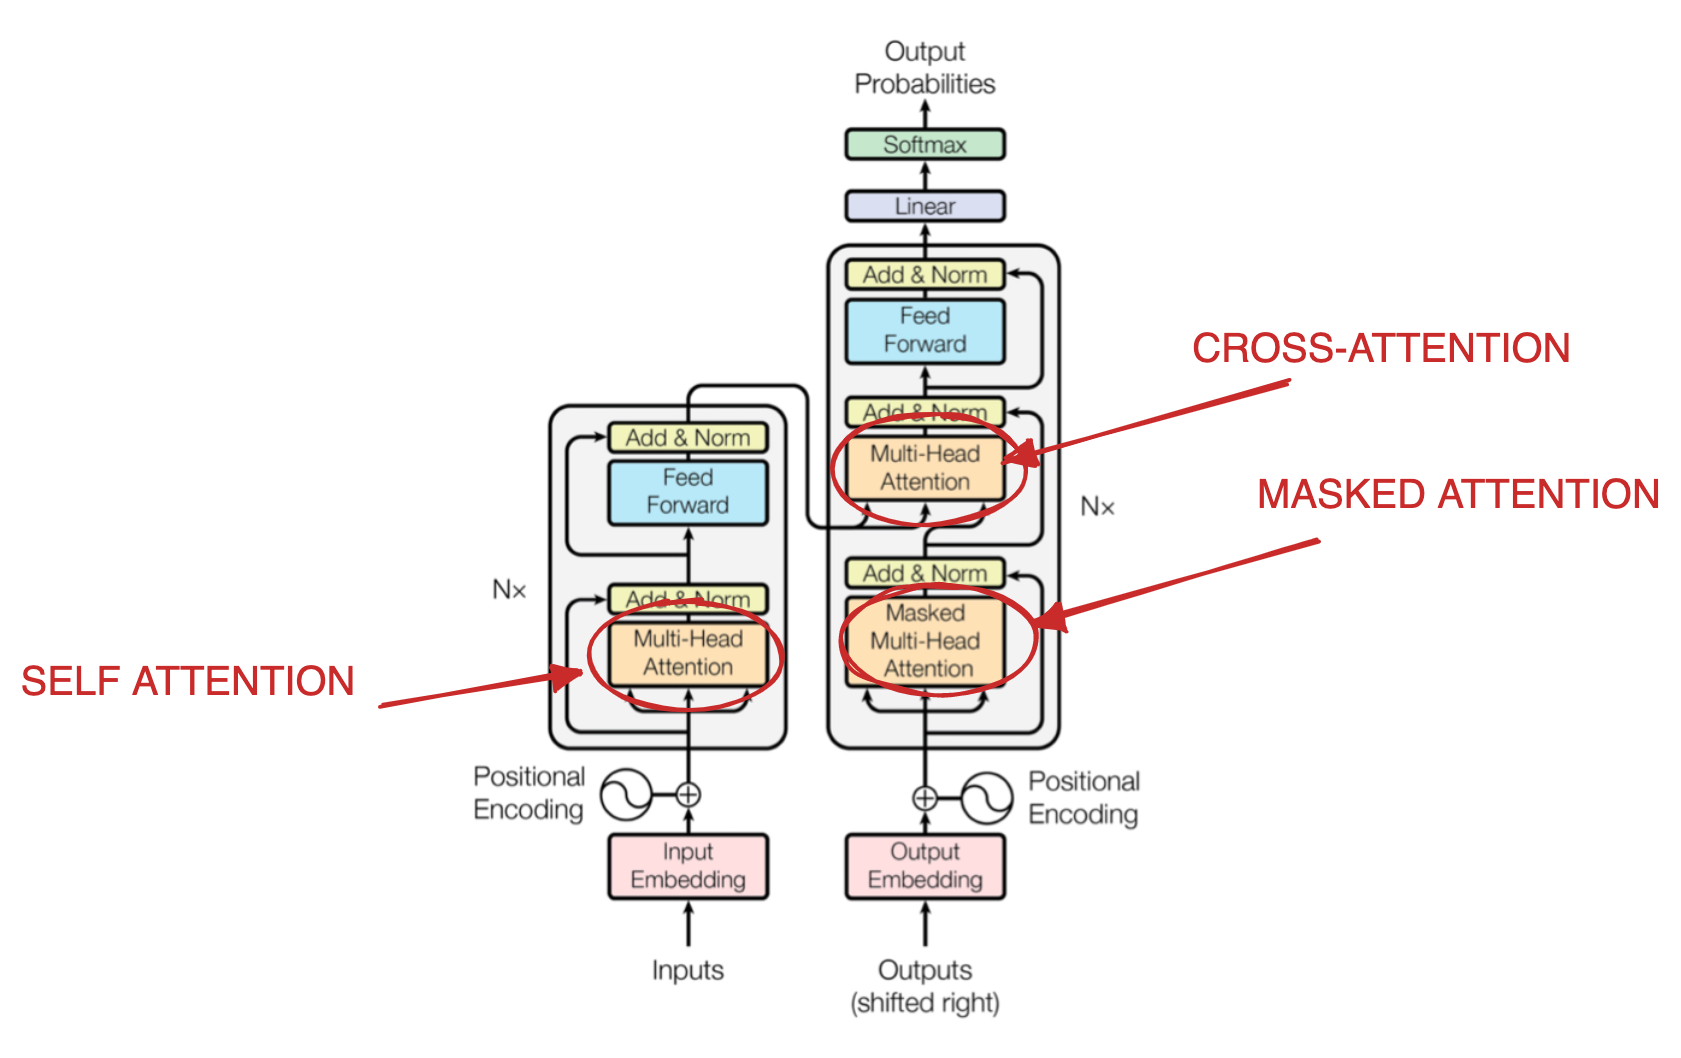
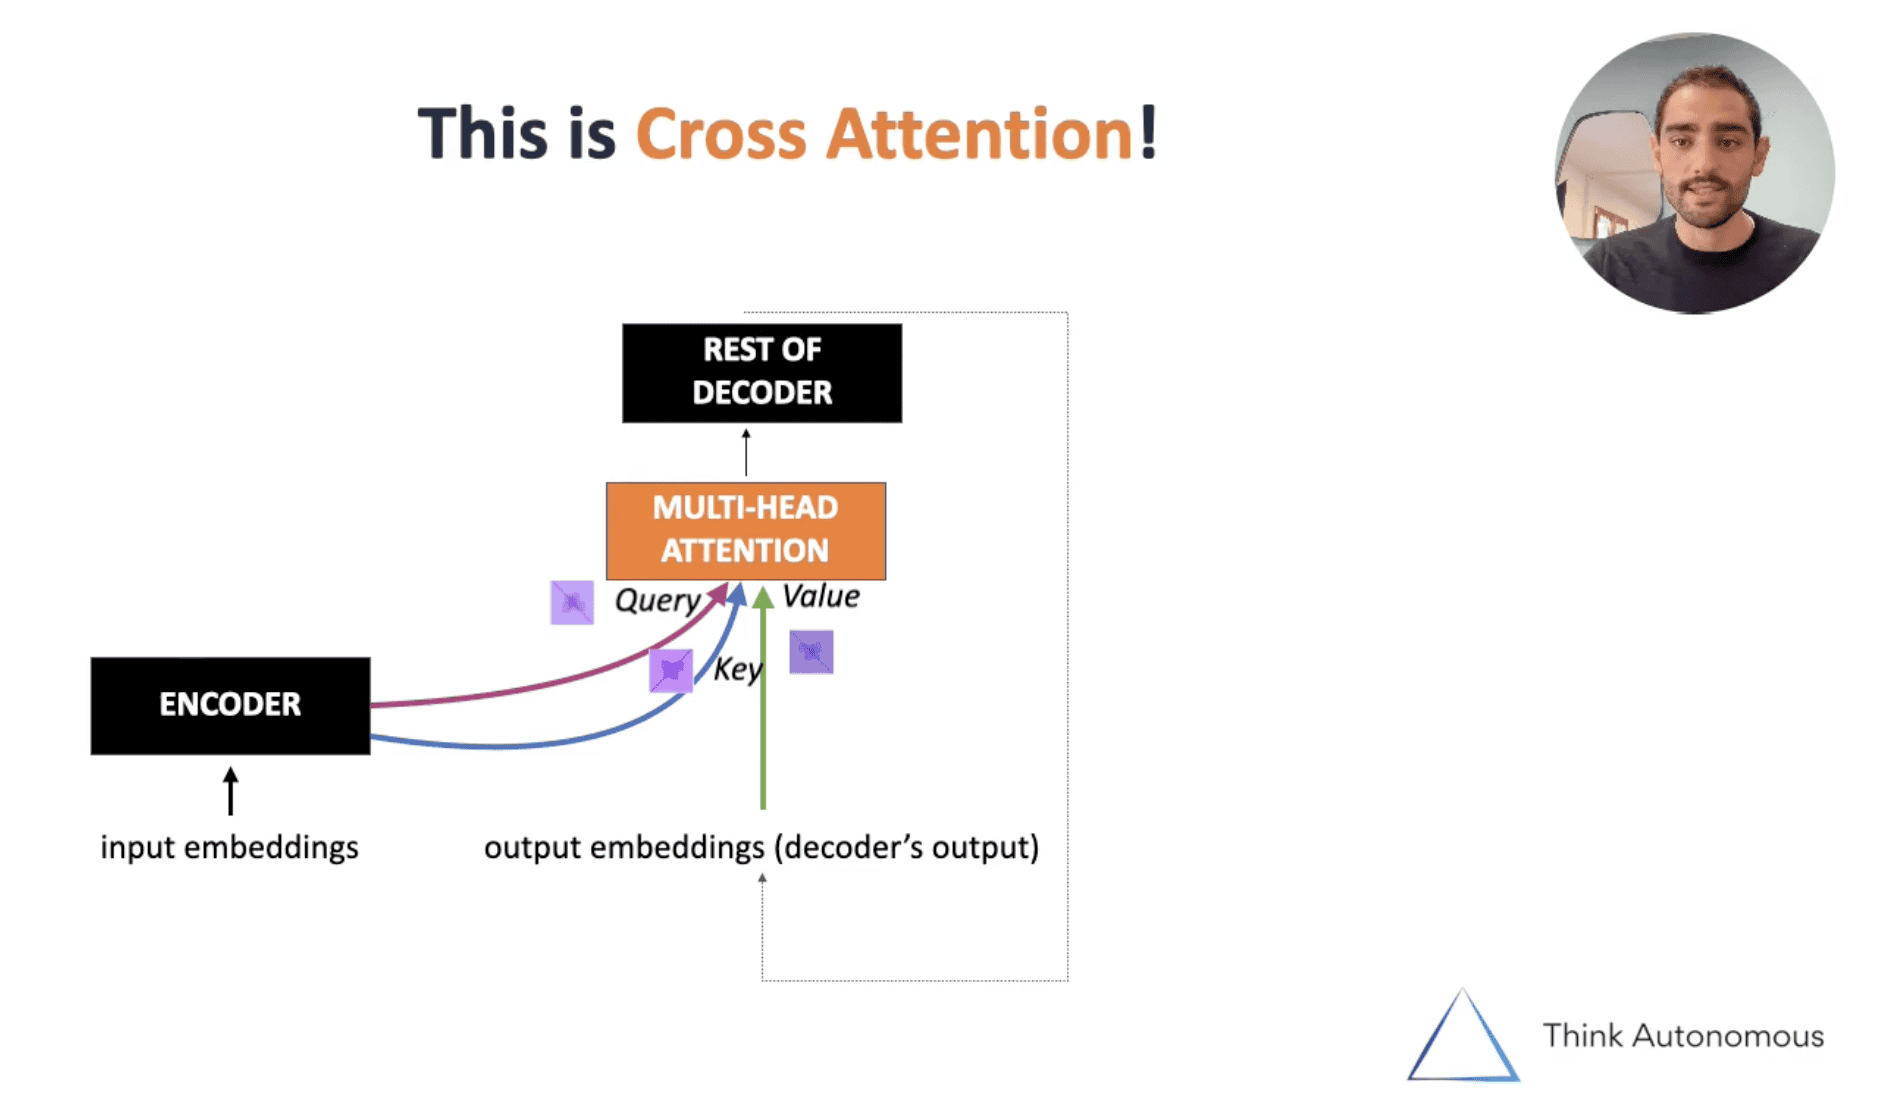
So what is Attention, and what are Transformers?
Attention is the simple idea that we humans don't scan every single pixel in our field of view, like a convolution would, but we focus on specific things.
These things can be objects, moving objects, or anything dangerous coming at us.
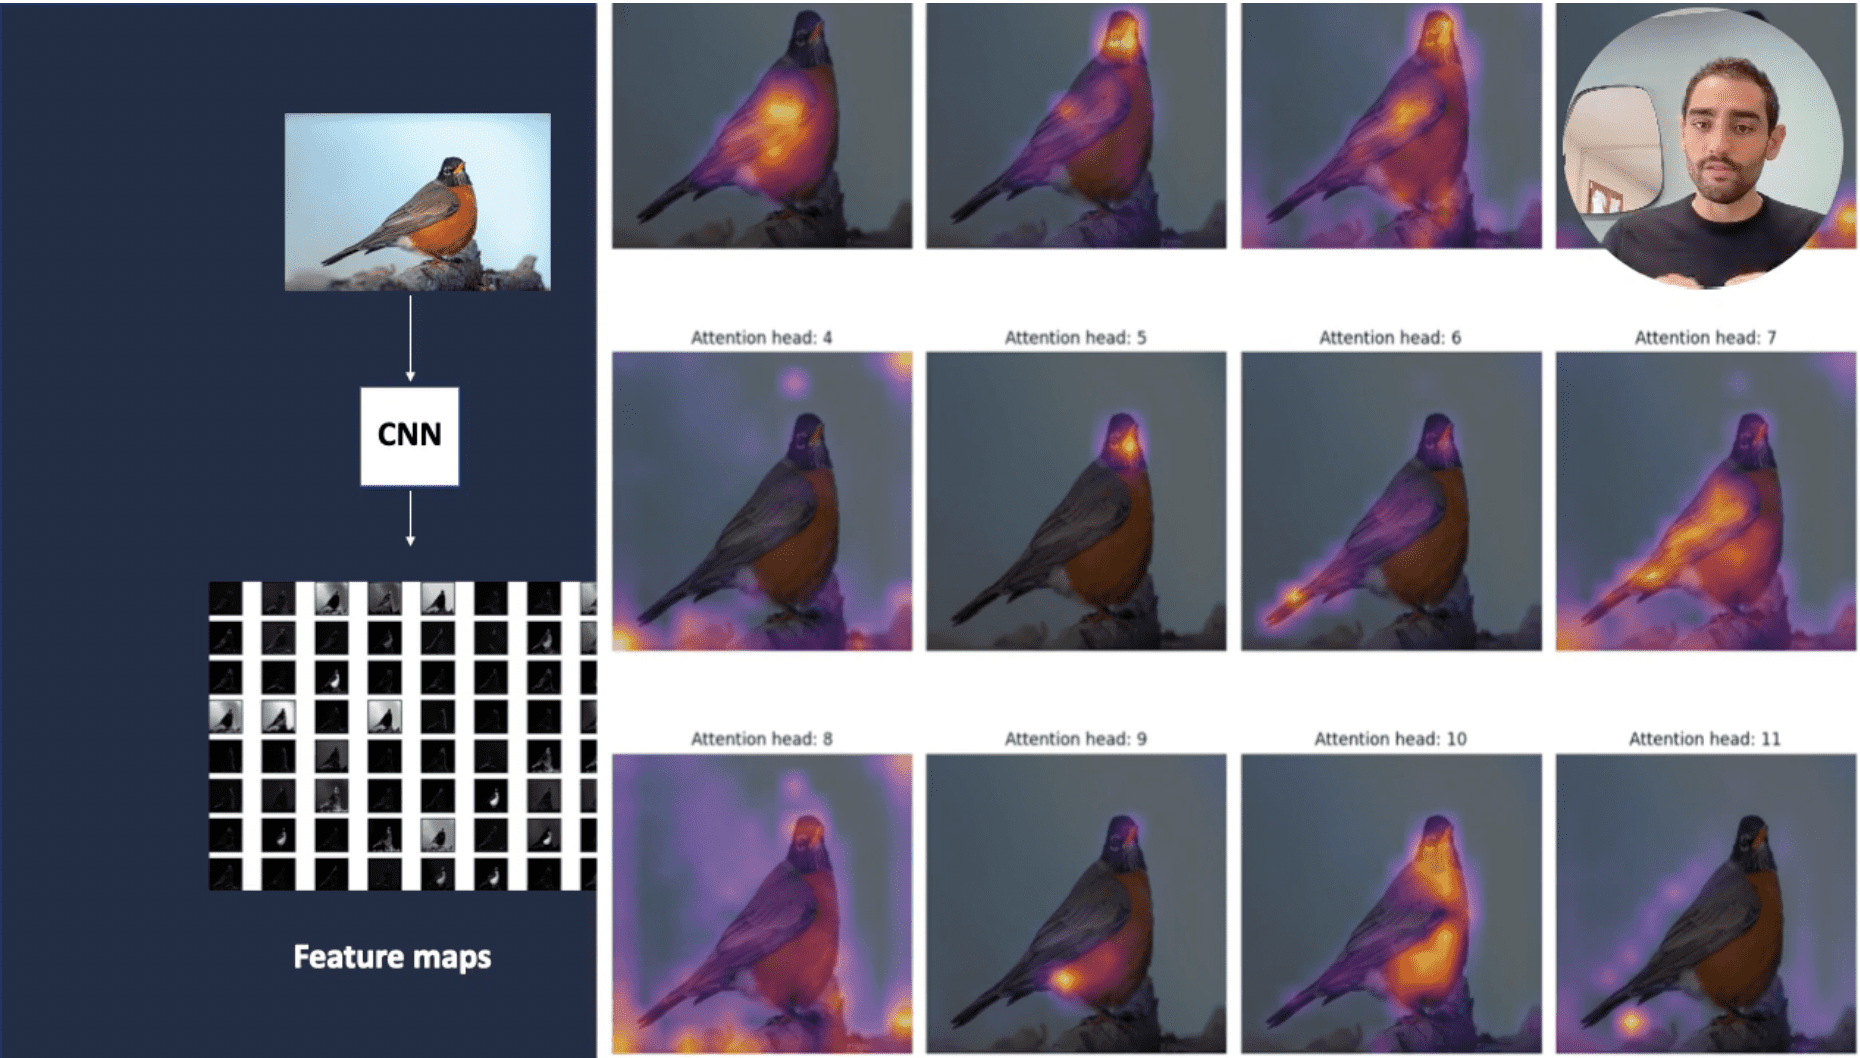
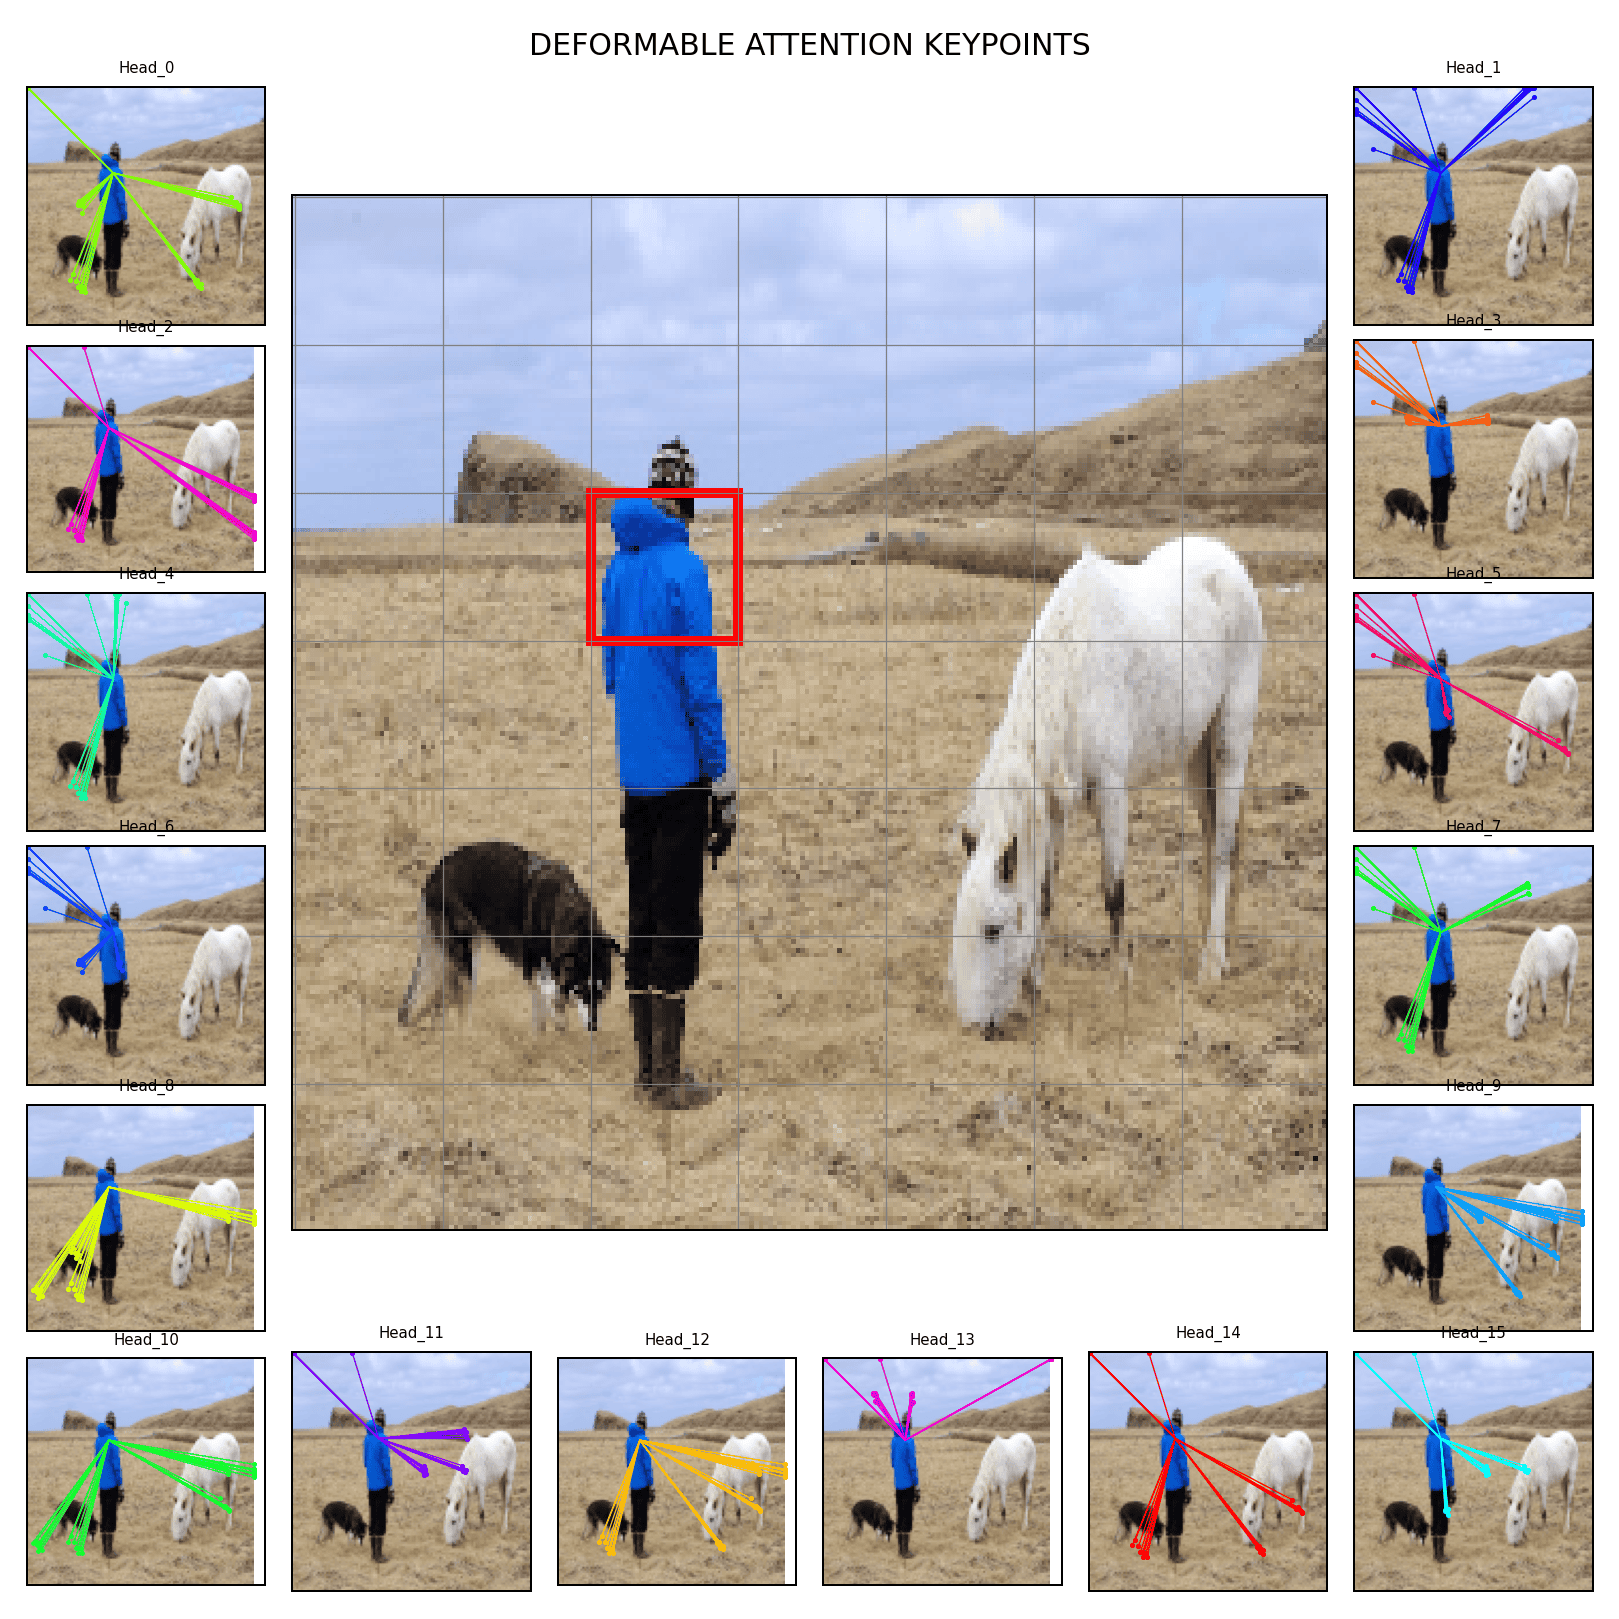
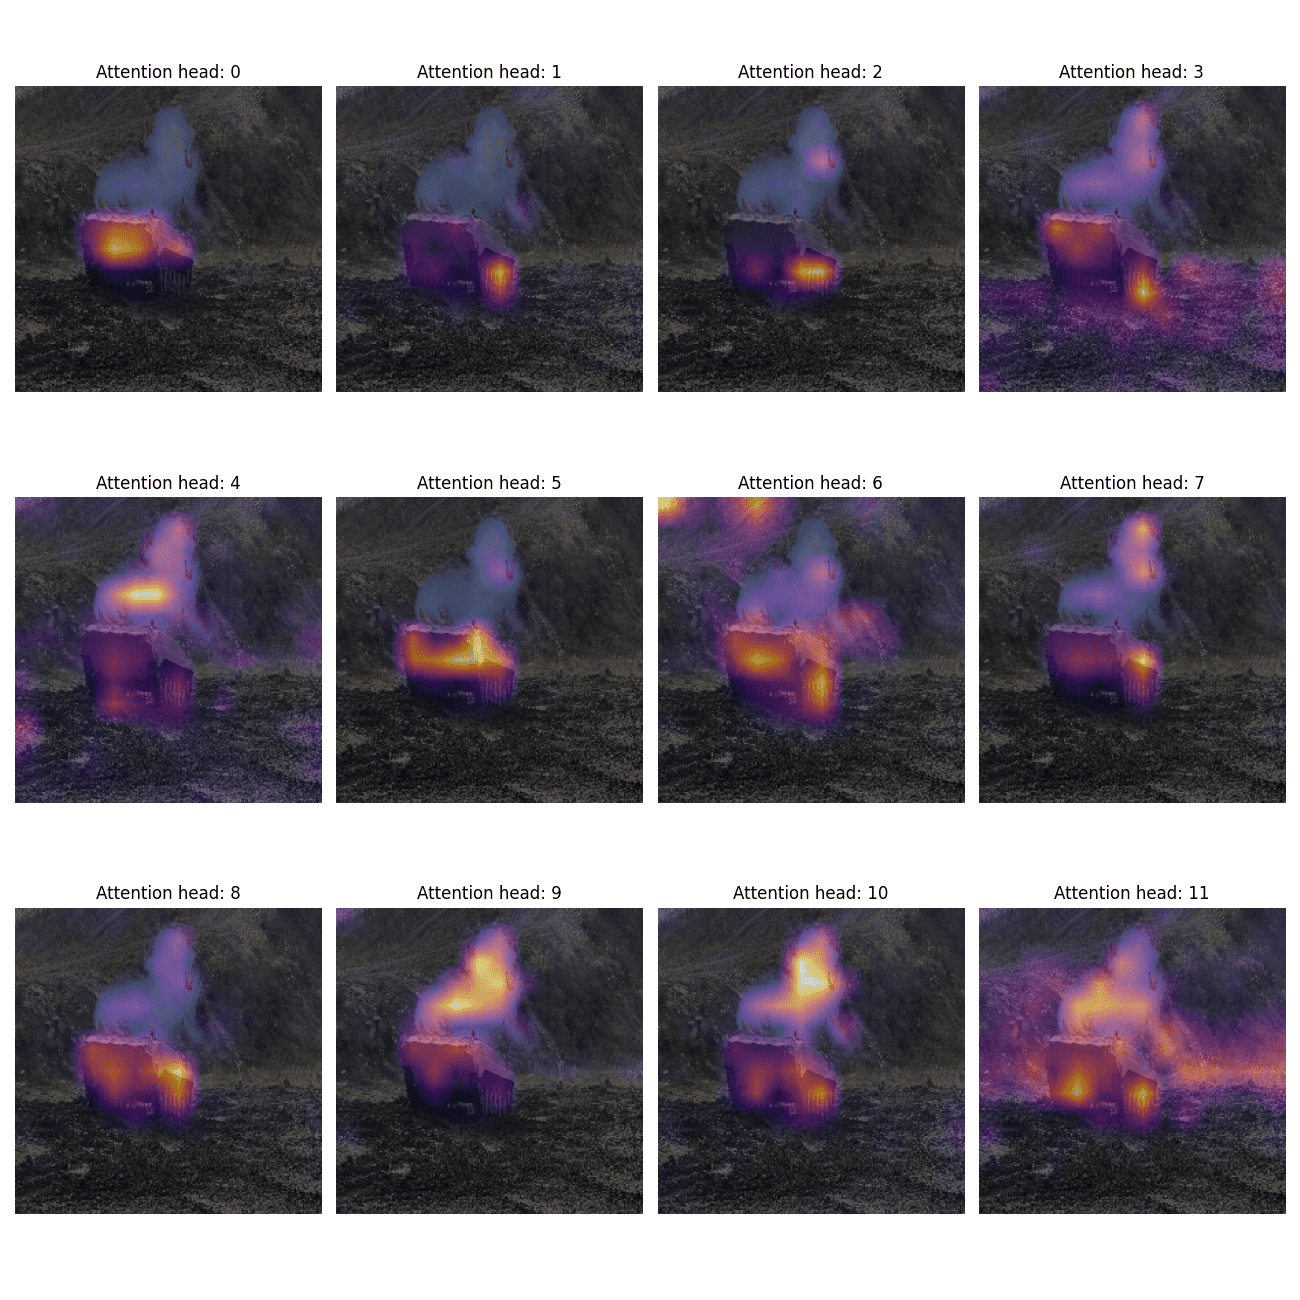
Attention means focus. And there is also Multi-Head Attention, that means focus on several parts.
And this is how Neural Networks should learn! Not by analyzing everything, but by learning what's to focus on, and what's not.
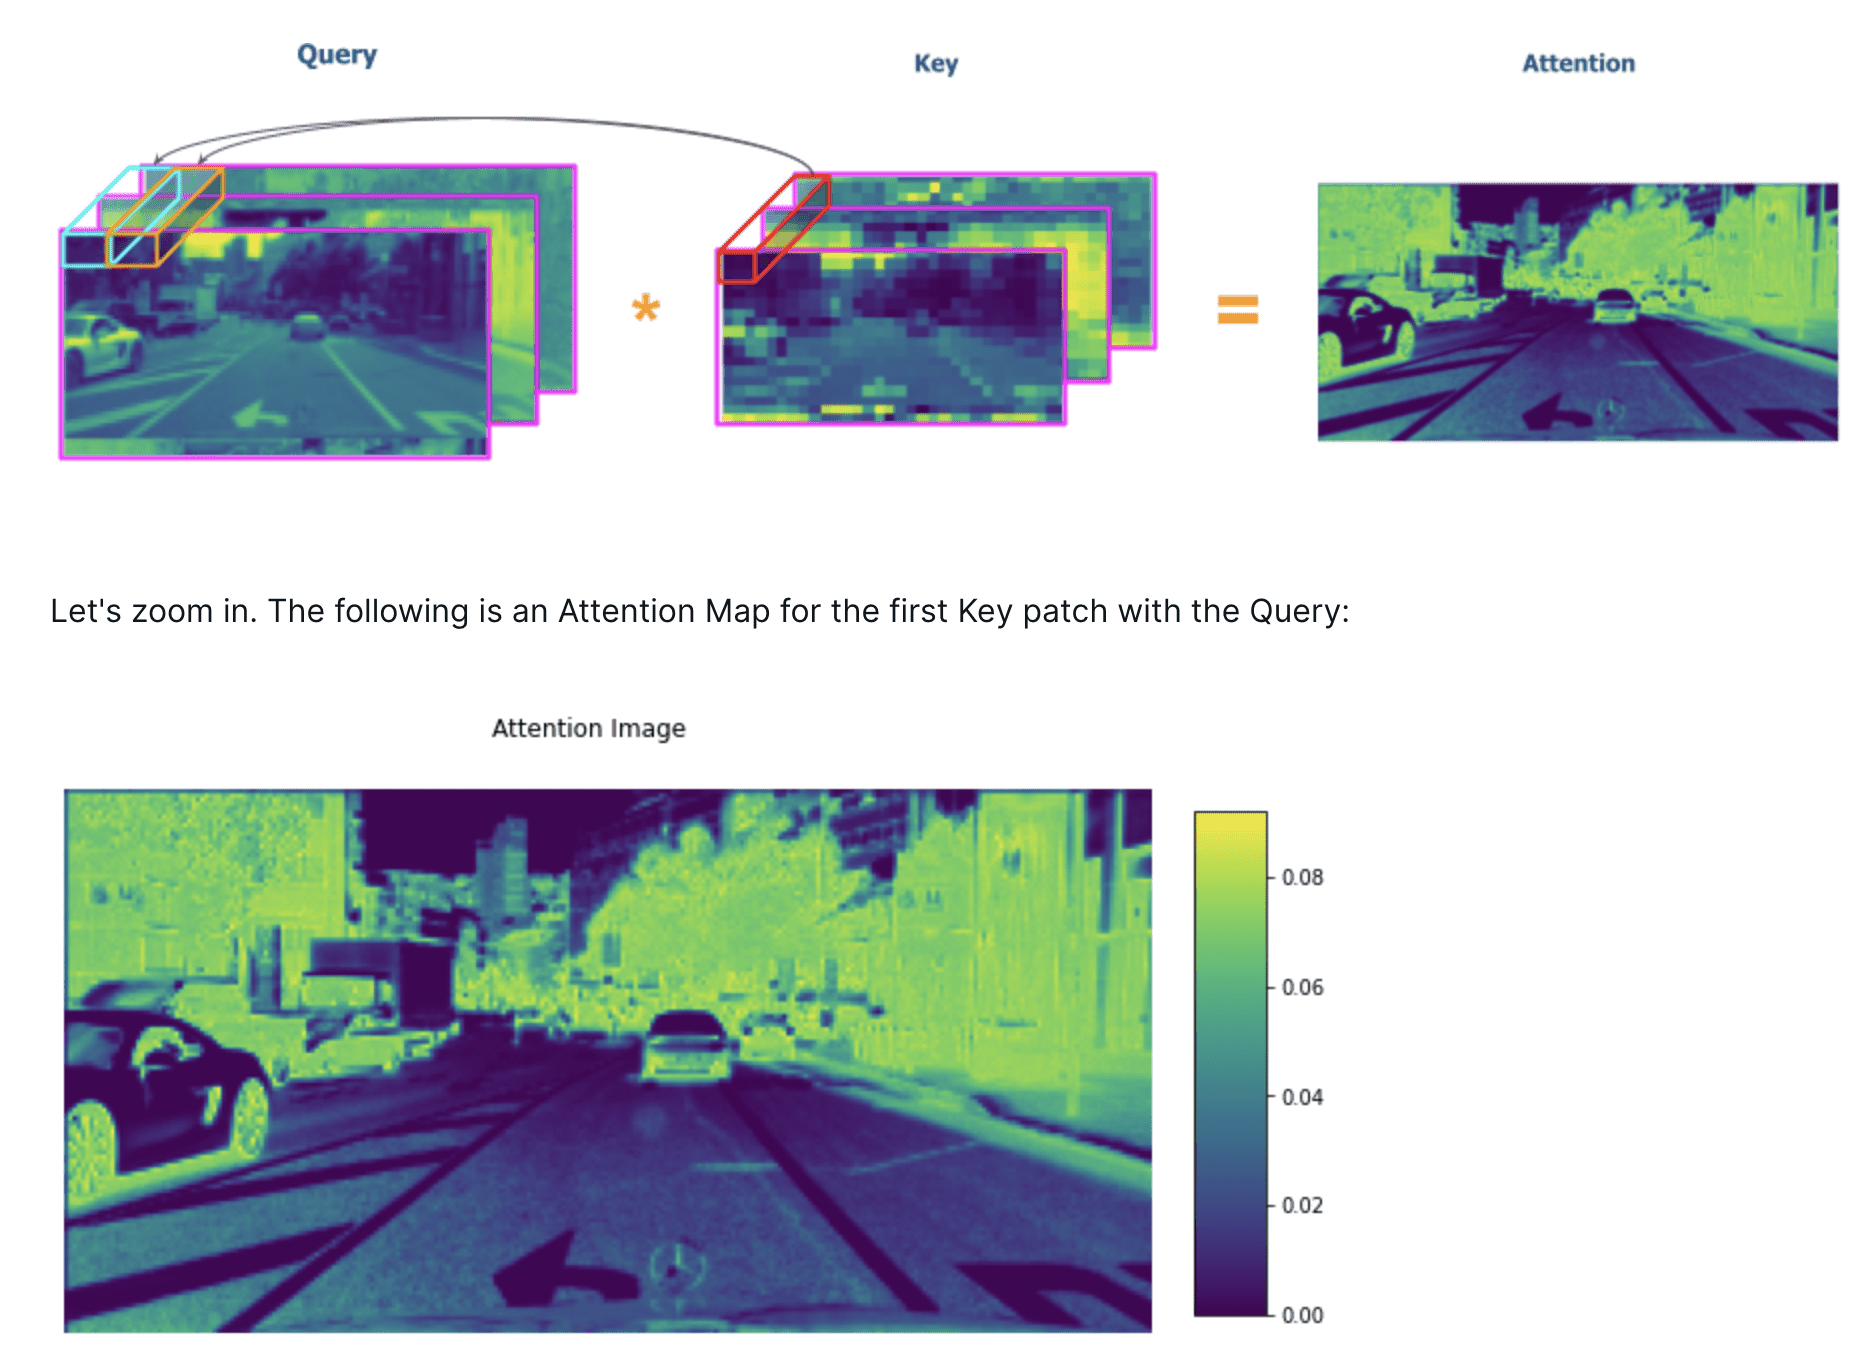
For example, take this video of self-driving car startup Wayve, where they build an "Attention Mask" that shows the vehicle 'Attention Map' switching with the traffic light:
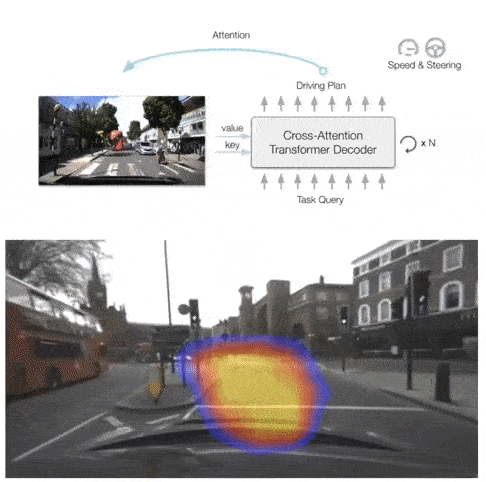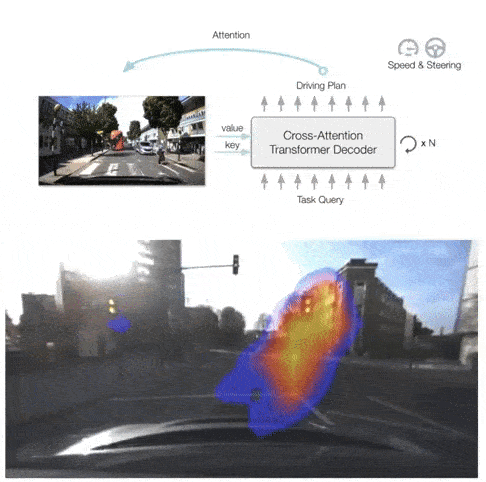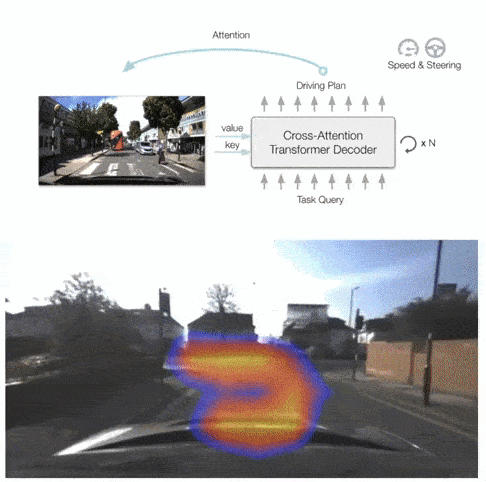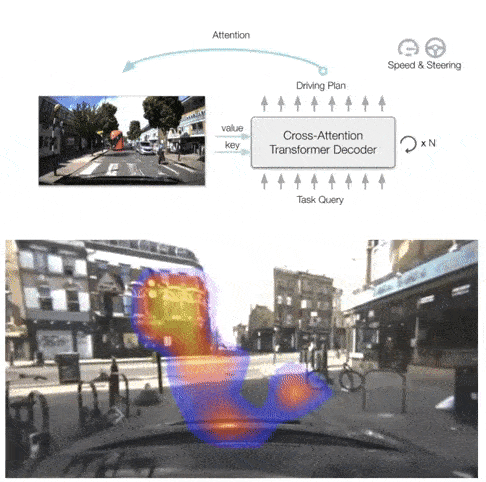
The network focuses on the traffic light when it's red, and on the street as soon as it's green. This is Attention!
And this is what we'll learn to build in this course.
Attention Maps, but more importantly: Neural Networks that use the Attention Block to implement cutting-edge image segmentation architectures!
But have you ever tried to learn attention?
For example, do you recognize the following scenes?
- "I've tried learning attention a few times already, but never really managed to commit".
- "I've watched a few tutorials, but I still feel like I don't know how to include this as part of my work"
- "Many of the breakthroughs in Deep Learning mention Transformers and Attention, but I still have no clue how to learn that easily"
Yes, Attention is hard to learn, and there is a good reason...
Most of the explanations available are targeted to NLP people, not us!
All the examples, analogies, and projects are designed for NLP applications like text translation, sentence prediction and others...
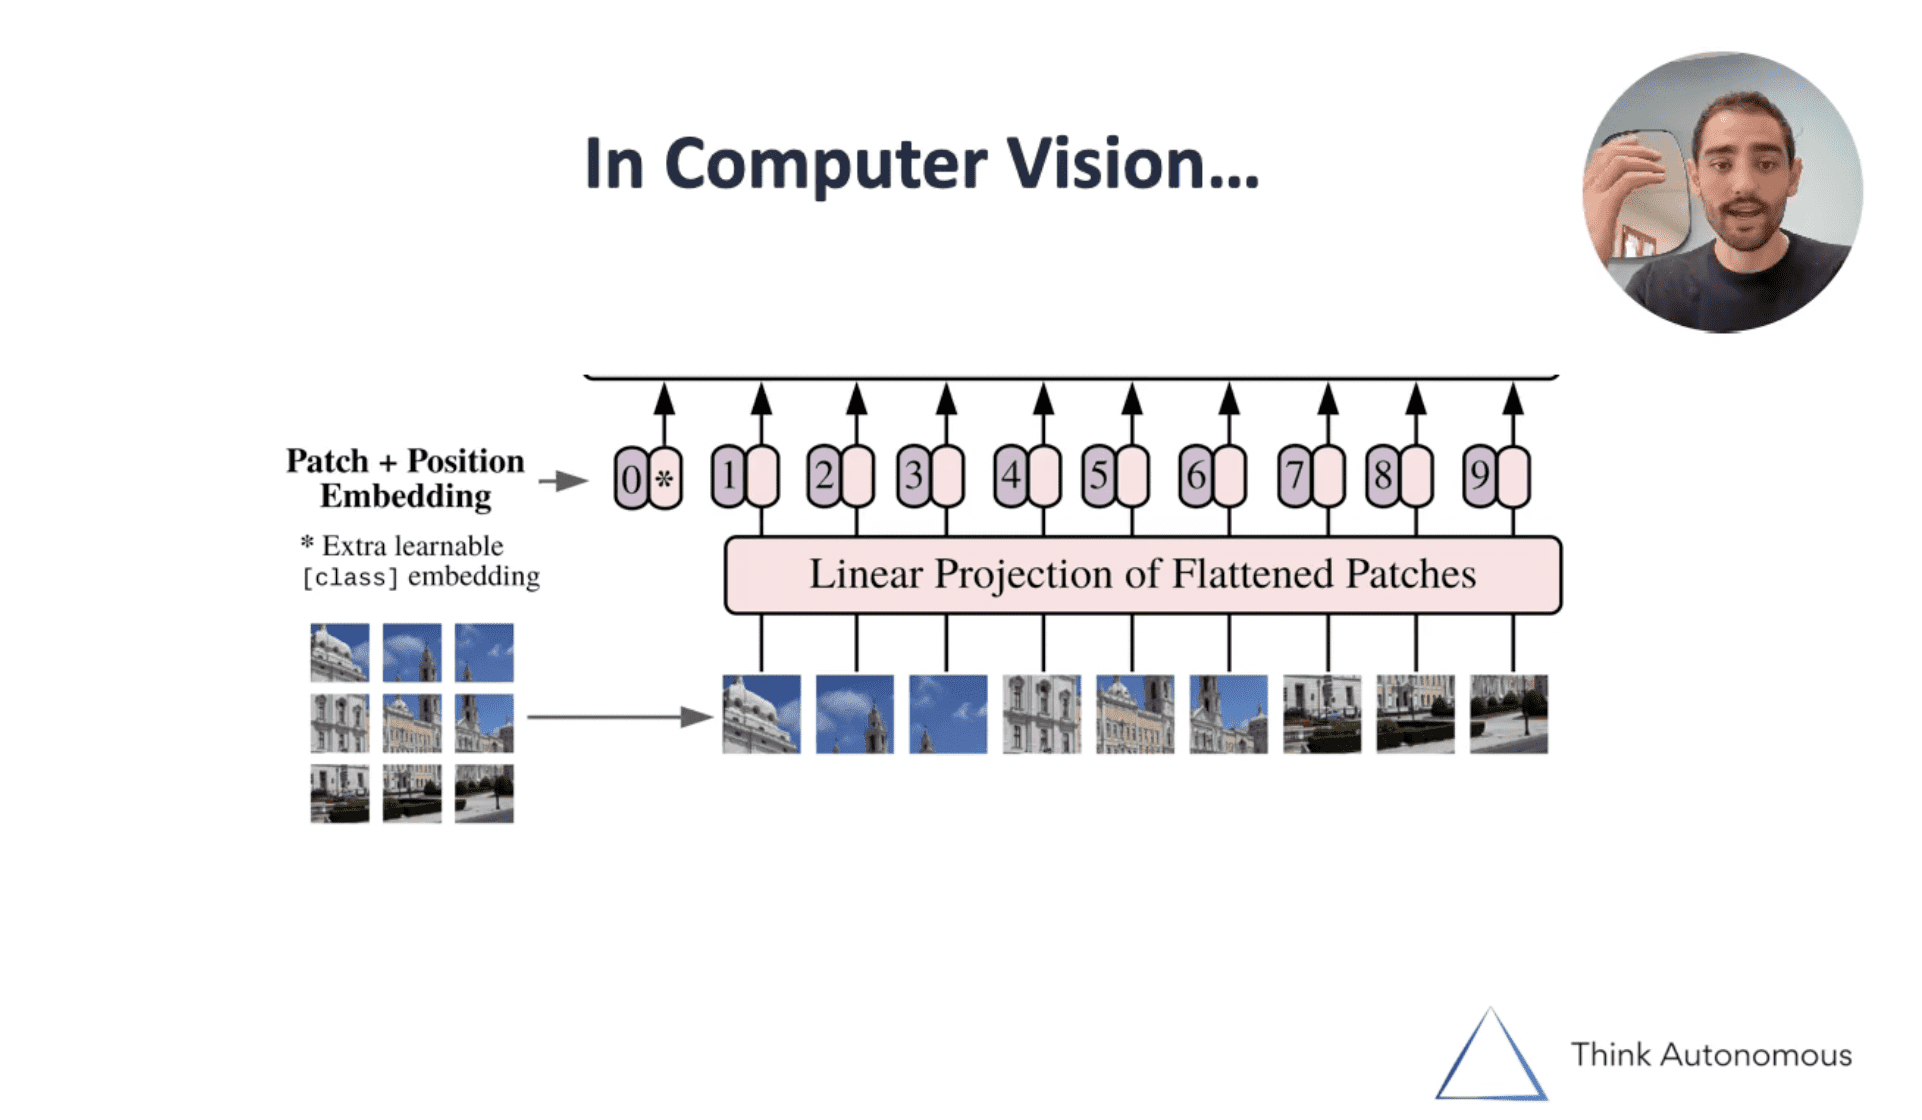
Transformers started with NLP, but it's now taking over the Computer Vision world.
And we're not NLP people, we are Computer Vision people.
We don't want to deal with sentences. Words converted to vectors. LSTMs and RNNs. We want images! Yes, images!
And it's even deeper than this:
We don't just want images.
If, like me, you started to learn Deep Learning with CNNs, your brain made its connections to learn.
For years.
Which means... You are hardwired to learn by looking at images!
Which is why, after months spent learning Attention and Transformers, and even hiring experts to understand how to build cutting-edge architectures that use Transformers for problems like object detection or image segmentation...
... I have compiled the first ever course on Transformers, but explained to Computer Vision people!
Which means that this course won't teach attention with sentences and LSTMs, but with images!
And with images and colors, your brain will make the connections easier.
So let's see the program: